↓ Skip to main content

Szilard Pafka

2021

Goodbye DataScience.LA, goodbye California!

Goodbye DataScience.LA, goodbye California!

·1 min
I (Szilard) started organizing meetups more than a decade ago (the LA R Users Group est. 2009 was the very first data meetup in the Los Angeles area). A few years later, a couple of us (Amelia, Leigh, Eduardo and I, and also several contributors) started a few more meetup groups (e.g. Data Science) and this very website DataScience.LA. However, in recent years my DataScience.LA Leadership Teammates relocated and now it’s my turn, I’m the last one to leave California (I’m very excited to move to Texas!). While we are ceasing all activities in LA now and this is the last update/post on this website, we will keep the existing/old content accessible for a while. It was a great pleasure running these events/this site and getting to know so many of you. LA has so many great data science folks! However, now it’s time to say goodbye, goodbye LA and California, and good luck to you all.
2020

2018

2017

R Meetup with Hadley Wickham

R Meetup with Hadley Wickham

·1 min
Update: Video of the 2nd half of the talk is here (1st half was not recorded, sorry): This video is no longer available on YouTube (original link). In our next meetup, we’ll have Hadley (I think no introduction needed). Packages made easy by Hadley Wickham
Meetup: Stream processing with R in AWS

Meetup: Stream processing with R in AWS

Update: Slides click here. Video recording here: This video is no longer available on YouTube (original link). Stream processing with R in AWS by Gergely Daróczi Abstract: R is rarely mentioned among the big data tools, although it’s fairly well scalable for most data science problems and ETL tasks. This talk presents an open-source R package to interact with Amazon Kinesis via the MultiLangDaemon bundled with the Amazon KCL to start multiple R sessions on a machine or cluster of nodes to process data from theoretically any number of Kinesis shards. Besides the technical background and a quick introduction on how Kinesis works, this talk will feature some stream processing use-cases at CARD.com, and will also provide an overview and hands-on demos on the related data infrastructure built on the top of Docker, Amazon ECS, ECR, KMS, Redshift and a bunch of third-party APIs.
Meetup: No-Bullshit Data Science

Meetup: No-Bullshit Data Science

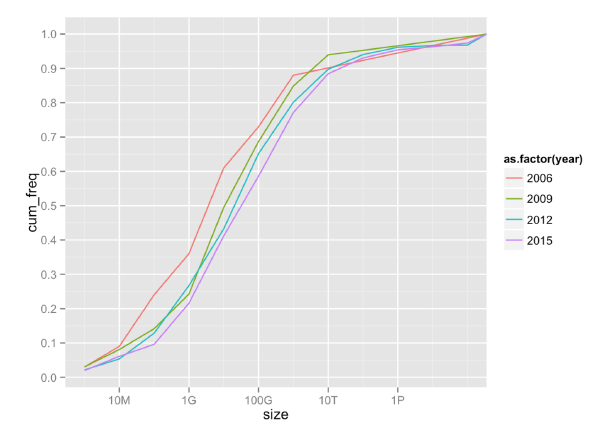
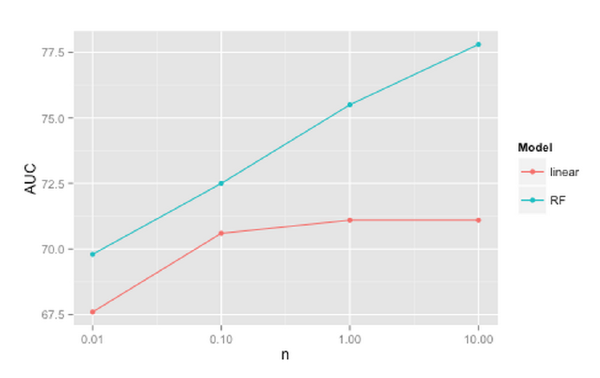
Update: Slides here: Slides: https://speakerdeck.com/szilard/machine-learning-meetup-febr-2017 Our next meetup: No-Bullshit Data Science by Szilard Pafka Abstract: While extracting business value from data has been performed by practitioners for decades, the last several years have seen an unprecedented amount of hype in this field. This hype has created not only unrealistic expectations in results, but also glamour in the usage of the newest tools assumably capable of extraordinary feats. In this talk I will apply the much needed methods of critical thinking and quantitative measurements (that data scientists are supposed to use daily in solving problems for their companies) to assess the capabilities of the most widely used software tools for data science. I will discuss in details two such analyses, one concerning the size of datasets used for analytics and the other one regarding the performance of machine learning software used for supervised learning.

2016

XGBoost workshop and meetup talk with Tianqi Chen

XGBoost workshop and meetup talk with Tianqi Chen

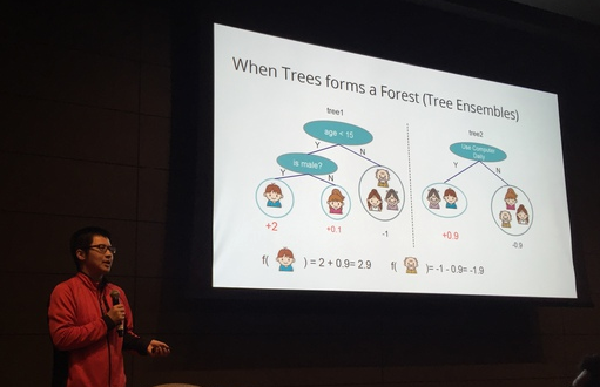
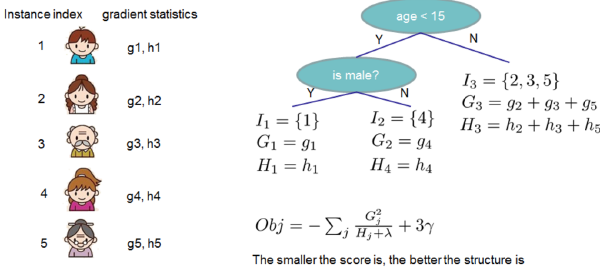
XGBoost is a fantastic open source implementation of Gradient Boosting Machines, a general purpose supervised learning method that achieves the highest accuracy on a wide range of datasets in practical applications. Deep learning is all the hype now, but apart from specific domains such as images, speech or text (i.e. problems with higher-level abstractions to be learnt and/or perception problems, where deep learning achieved some remarkable results indeed), it is usually outperformed by Gradient Boosting in a majority of general business domains and supervised learning applications. Proof of this and also because XGBoost has an easy-to-use interface from both R and Python, XGBoost has become a favorite tool in Kaggle competitions. Besides feature engineering, cross-validation and ensembling, XGBoost is a key ingredient for achieving the highest accuracy in many data science competitions and more importantly in practical applications.
XGBoost: meetup announcement

XGBoost: meetup announcement

XGBoost is a fantastic open source implementation of Gradient Boosting Machines, one of the most accurate general purpose supervised learning algorithms. With interfaces from both R and Python among others, it has become a favorite tool in Kaggle competitions, and it’s also widely used in real-world applications. In this meetup we’ll have a talk from the best person on the topic,Tianqi Chen, main author of XGBoost.
Deep Learning @Whisper

Deep Learning @Whisper

Deep Learning @Whisper talk by Nick Stucky-Mack Video now available, thank you to community member Carl Mullins for providing video services: ▶ Deep Learning @Whisper THU, MAY 12 AT 6 00 PM, VENICE, CA In this talk we will discuss how Whisper uses machine learning for natural language processing tasks. We will focus on how Whisper applies deep learning to moderate content created by its more than 20 million monthly active users. The talk will explore the problem of short text classification, and will cover Whisper’s choices in machine learning models, software development, and hardware.
What has Kaggle learned from 2 million machine learning models?

What has Kaggle learned from 2 million machine learning models?

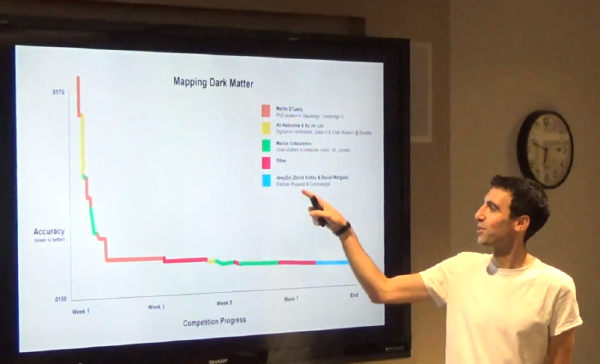
What has Kaggle learned from 2 million machine learning models? Anthony Goldbloom, founder and CEO of Kaggle UPDATE:Video recording of the talk available here Kaggle is a community of almost 450K data scientists who have built almost 2MM machine learning models to participate in our competitions. Data scientists come to Kaggle to learn, collaborate and develop the state of the art in machine learning. This talk will cover some of the lessons on winning techniques we have learned from the Kaggle community.

2015

Winning Data Science Competitions

Winning Data Science Competitions

·1 min
Our next Data Science meetup: Winning Data Science Competitions by Jeong-Yoon Lee In this talk, I am going to share my experiences in data science competitions. After an overview of the competition structure and best practices, I will present the 1st prize winner’s solution for KDD Cup 2015 with the behind-the-scenes story.
Benchmarking Random Forest Implementations

Benchmarking Random Forest Implementations

I currently have the need for machine learning tools that can deal with observations of the order of 10 millions in the context of binary classification. That kind of data is a few GBs in size and it fits comfortably nowadays in the RAM of a decent single machine. It is a trivial task for linear models, as there are plenty of open source tools that can train a logistic regression with this amount of data on a single machine in a few seconds, even while using only 1 processor core (many of these tools are single-threaded). Linear models are also the gold standard of large-scale machine learning that can run on clusters, processing very large distributed datasets.
Data Science/Statistics/R @Google

Data Science/Statistics/R @Google

This meetup will be hosted by Google and we’ll have Peter Lipman and Pete Meyer talk about the data science/statistics projects they have been working on at Google. Human Evaluation Comparisons: Common Framework with Applications We designed a study to determine whether being on device influenced a quality evaluator’s perception of ads quality. Here, we present a common framework, developed into an internal R package, that was used to analyze the study.
DW/BI/Analytics Meetup Summary: Inaugural Event

DW/BI/Analytics Meetup Summary: Inaugural Event

The LA Data Warehouse, Business Analytics and Analytics meetup had a fantastic first event with a great audience (full house), an awesome host (thanks Edmunds: Punnoose for taking the lead and the Team onsite and helping) and a great mix of 3 talks overviewing the field.