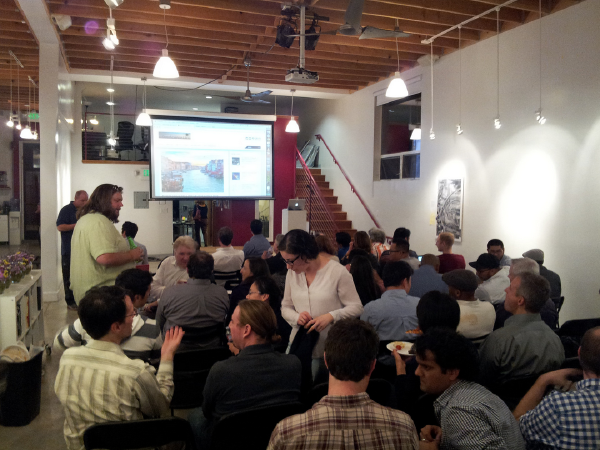
On May 14th at the Venice Arts Center, the Los Angeles Python and Data Science communities were fortunate to hear a talk from world-renowned expert and CEO of Dato, Carlos Guestrin. Often times when you have a meetup where a presenter is tightly identified with a company, the concern is that the presentation will fundamentally become a product pitch. We had nothing to be worried about in this case - Carlos presented for nearly an hour on a wide range of subjects from how the Machine Learning pipeline has changed over time to Deep Learning!
*** EVENTBRITE LINK HERE ***
PyDSLA - Dato: A Platform for Practical, Large-Scale Machine Learning
Join PyDSLA for a talk by Carlos Guestrin about Presents Practical, Large-Scale Machine Learning in python.
Summary:
Data Science is perhaps the hottest profession on the market today. Folks with backgrounds ranging from Statistics and Physics to Engineering and Computer Science are eager and excited to transition to this field. However, designing and deploying data analysis and machine learning apps at scale is a significant challenge to overcome: For some folks, machine learning algorithms and methods can be obscure, too mathy, and disconnected from practice. For others, writing and deploying scalable software requires significant effort, which distracts them from focusing on their deep analytic efforts.
Join PyDSLA for a talk by Matthew Rocklin about the high level APIs being developed for Python for expressive data manipulation and analysis.
Summary:
Pandas and NumPy serve us well. They give interactive high-level access to efficient low-level code. As datasets grow larger than memory this low-level code becomes obsolete but the high-level interface remains valuable. Blaze connects that high-level interface to a number of other computational systems like SQL, Mongo, or Spark, extending the scope of interactive analysis. In this talk we go over common use cases and Blaze as well as a bit of its internal design.