↓ Skip to main content

big data

2017

Meetup: Stream processing with R in AWS

Meetup: Stream processing with R in AWS

Update: Slides click here. Video recording here: This video is no longer available on YouTube (original link). Stream processing with R in AWS by Gergely Daróczi Abstract: R is rarely mentioned among the big data tools, although it’s fairly well scalable for most data science problems and ETL tasks. This talk presents an open-source R package to interact with Amazon Kinesis via the MultiLangDaemon bundled with the Amazon KCL to start multiple R sessions on a machine or cluster of nodes to process data from theoretically any number of Kinesis shards. Besides the technical background and a quick introduction on how Kinesis works, this talk will feature some stream processing use-cases at CARD.com, and will also provide an overview and hands-on demos on the related data infrastructure built on the top of Docker, Amazon ECS, ECR, KMS, Redshift and a bunch of third-party APIs.
Meetup: No-Bullshit Data Science

Meetup: No-Bullshit Data Science

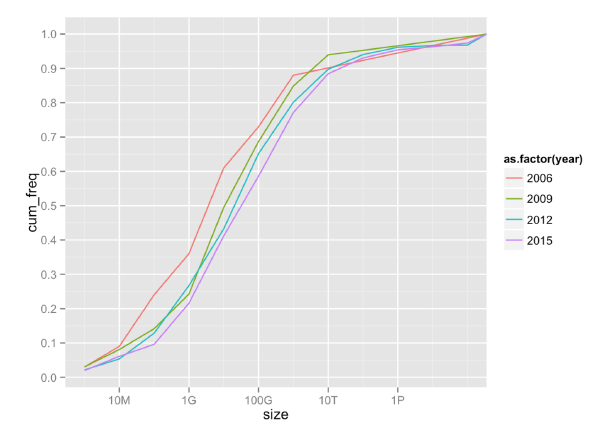
Update: Slides here: Slides: https://speakerdeck.com/szilard/machine-learning-meetup-febr-2017 Our next meetup: No-Bullshit Data Science by Szilard Pafka Abstract: While extracting business value from data has been performed by practitioners for decades, the last several years have seen an unprecedented amount of hype in this field. This hype has created not only unrealistic expectations in results, but also glamour in the usage of the newest tools assumably capable of extraordinary feats. In this talk I will apply the much needed methods of critical thinking and quantitative measurements (that data scientists are supposed to use daily in solving problems for their companies) to assess the capabilities of the most widely used software tools for data science. I will discuss in details two such analyses, one concerning the size of datasets used for analytics and the other one regarding the performance of machine learning software used for supervised learning.

2016

What has Kaggle learned from 2 million machine learning models?

What has Kaggle learned from 2 million machine learning models?

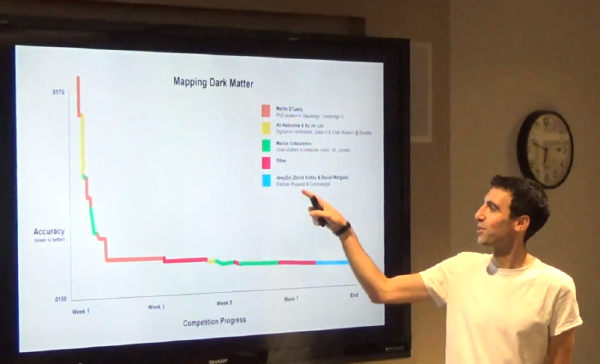
What has Kaggle learned from 2 million machine learning models? Anthony Goldbloom, founder and CEO of Kaggle UPDATE:Video recording of the talk available here Kaggle is a community of almost 450K data scientists who have built almost 2MM machine learning models to participate in our competitions. Data scientists come to Kaggle to learn, collaborate and develop the state of the art in machine learning. This talk will cover some of the lessons on winning techniques we have learned from the Kaggle community.

2015

R and Impala: it's better to KISS than using Java

R and Impala: it's better to KISS than using Java

One of the best things I like in working at CARD.com is that I am not only crunching R code in 24/7, but I also have the chance to interact with and improve the related data infrastructure with some interesting technologies. After joining the company in January, I soon realized that while Impala is a very powerful database for handling data that do not comfortably fit in MySQL, it’s still not as fast as one might expect when querying large amount of data from R. Sometimes I had to wait several minutes for a query to run! So I used this spare time to think about how to improve the workflow.
Announcing Meetup! Lior Abraham of Inter|Ana

Announcing Meetup! Lior Abraham of Inter|Ana

Click HERE to sign up on Eventbrite! This is the second event of the new Data Warehouse, Business Intelligence and Analytics meetup. Talks: 1. Eduardo Arino de la Rubia: MySQL to Vertica with Tungsten Replicator In this very (very) short talk, I will discuss how you can, for free, stream your MySQL data to a Vertica Community Edition cluster, and do near real-time analytics on up to 1TB of data.
DW/BI/Analytics Meetup Summary: Inaugural Event

DW/BI/Analytics Meetup Summary: Inaugural Event

The LA Data Warehouse, Business Analytics and Analytics meetup had a fantastic first event with a great audience (full house), an awesome host (thanks Edmunds: Punnoose for taking the lead and the Team onsite and helping) and a great mix of 3 talks overviewing the field.

2014

Announcing Partnership with LA Big Data Community

Announcing Partnership with LA Big Data Community

Today I am happy to announce that we are expanding our partnership on several fronts with my friend Subash D’Souza, a leader of the Big Data community in LA. During the past few years I have been organizing several data science meetups in Los Angeles (LA R, DataVis LA, Data Science/Machine Learning) and Subash has provided the same kind of leadership on the big data front (LA Hadoop, HBase, LA Big Data). While I think of big data as primarily technology and of data science as a blend of statistics and technology (and not only for large data sets), there is clearly a significant overlap between these two fields. Considering this overlap, we have already been collaborating for some time regarding these various meetups, e.g. organizing joint events or speaking at one another’s meetups.