↓ Skip to main content

data science

2019

2018

2017

R Meetup with Hadley Wickham

R Meetup with Hadley Wickham

·1 min
Update: Video of the 2nd half of the talk is here (1st half was not recorded, sorry): This video is no longer available on YouTube (original link). In our next meetup, we’ll have Hadley (I think no introduction needed). Packages made easy by Hadley Wickham
Meetup: Stream processing with R in AWS

Meetup: Stream processing with R in AWS

Update: Slides click here. Video recording here: This video is no longer available on YouTube (original link). Stream processing with R in AWS by Gergely Daróczi Abstract: R is rarely mentioned among the big data tools, although it’s fairly well scalable for most data science problems and ETL tasks. This talk presents an open-source R package to interact with Amazon Kinesis via the MultiLangDaemon bundled with the Amazon KCL to start multiple R sessions on a machine or cluster of nodes to process data from theoretically any number of Kinesis shards. Besides the technical background and a quick introduction on how Kinesis works, this talk will feature some stream processing use-cases at CARD.com, and will also provide an overview and hands-on demos on the related data infrastructure built on the top of Docker, Amazon ECS, ECR, KMS, Redshift and a bunch of third-party APIs.
Meetup: No-Bullshit Data Science

Meetup: No-Bullshit Data Science

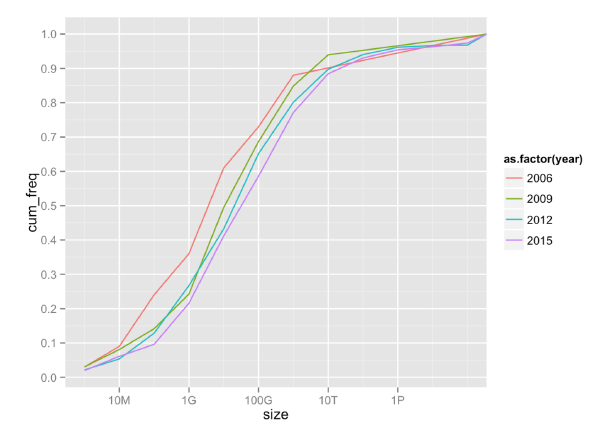
Update: Slides here: Slides: https://speakerdeck.com/szilard/machine-learning-meetup-febr-2017 Our next meetup: No-Bullshit Data Science by Szilard Pafka Abstract: While extracting business value from data has been performed by practitioners for decades, the last several years have seen an unprecedented amount of hype in this field. This hype has created not only unrealistic expectations in results, but also glamour in the usage of the newest tools assumably capable of extraordinary feats. In this talk I will apply the much needed methods of critical thinking and quantitative measurements (that data scientists are supposed to use daily in solving problems for their companies) to assess the capabilities of the most widely used software tools for data science. I will discuss in details two such analyses, one concerning the size of datasets used for analytics and the other one regarding the performance of machine learning software used for supervised learning.

2016

How-to organize a satRday conference (v0.1)

How-to organize a satRday conference (v0.1)

·9 mins
It has been over 2 months since the first satRday conference ended and I shared some quick impressions on that, where I also promised a follow-up post on my experiences as ending up being the main organizer of the event – this is what you are reading now. Although the idea was born at the EARL Boston conference last year, and I decided to take part in the project while living in Los Angeles – the conference took place in Budapest after all as logistics seemed to be easier there thanks to my closer relationship to the Hungarian R User Group.
PyDSLA: Talks from the LA Data Science Community

PyDSLA: Talks from the LA Data Science Community

REGISTER HERE ON EVENTBRITE DATE AND TIME Wed, November 2, 2016 6:30 PM – 9:30 PM PDT Come to the PyDSLA November Meetup to hear talks from the community! In the last month, the organizers of the PyDSLA Meetup sent out a call for speakers, and the community answered with a number of great members coming forward willing and able to talk about some of the cool ways they are using the Python Data Science ecosystem to do cool stuff.
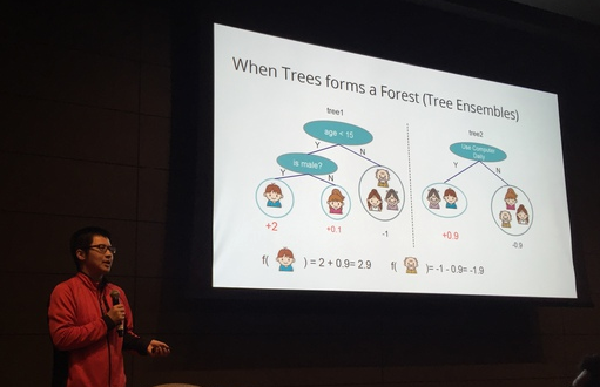
XGBoost workshop and meetup talk with Tianqi Chen

XGBoost workshop and meetup talk with Tianqi Chen

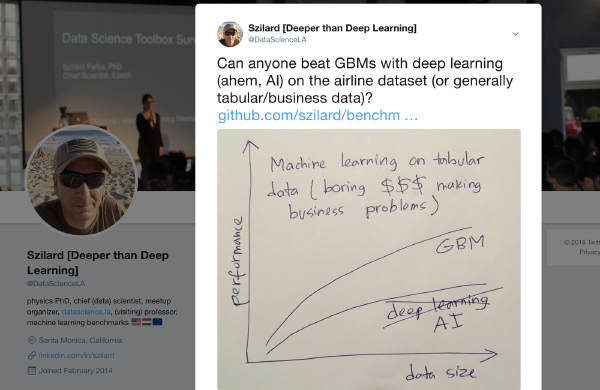
XGBoost is a fantastic open source implementation of Gradient Boosting Machines, a general purpose supervised learning method that achieves the highest accuracy on a wide range of datasets in practical applications. Deep learning is all the hype now, but apart from specific domains such as images, speech or text (i.e. problems with higher-level abstractions to be learnt and/or perception problems, where deep learning achieved some remarkable results indeed), it is usually outperformed by Gradient Boosting in a majority of general business domains and supervised learning applications. Proof of this and also because XGBoost has an easy-to-use interface from both R and Python, XGBoost has become a favorite tool in Kaggle competitions. Besides feature engineering, cross-validation and ensembling, XGBoost is a key ingredient for achieving the highest accuracy in many data science competitions and more importantly in practical applications.
XGBoost: meetup announcement

XGBoost: meetup announcement

XGBoost is a fantastic open source implementation of Gradient Boosting Machines, one of the most accurate general purpose supervised learning algorithms. With interfaces from both R and Python among others, it has become a favorite tool in Kaggle competitions, and it’s also widely used in real-world applications. In this meetup we’ll have a talk from the best person on the topic,Tianqi Chen, main author of XGBoost.
Deep Learning @Whisper

Deep Learning @Whisper

Deep Learning @Whisper talk by Nick Stucky-Mack Video now available, thank you to community member Carl Mullins for providing video services: ▶ Deep Learning @Whisper THU, MAY 12 AT 6 00 PM, VENICE, CA In this talk we will discuss how Whisper uses machine learning for natural language processing tasks. We will focus on how Whisper applies deep learning to moderate content created by its more than 20 million monthly active users. The talk will explore the problem of short text classification, and will cover Whisper’s choices in machine learning models, software development, and hardware.
What has Kaggle learned from 2 million machine learning models?

What has Kaggle learned from 2 million machine learning models?

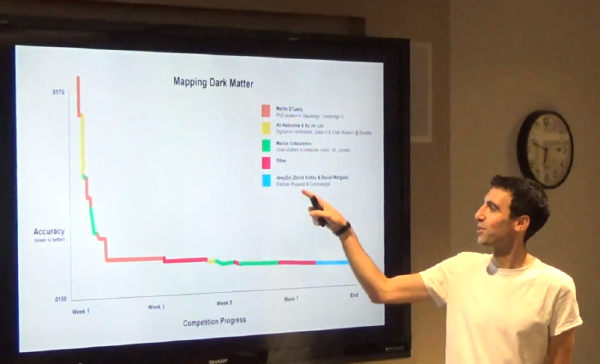
What has Kaggle learned from 2 million machine learning models? Anthony Goldbloom, founder and CEO of Kaggle UPDATE:Video recording of the talk available here Kaggle is a community of almost 450K data scientists who have built almost 2MM machine learning models to participate in our competitions. Data scientists come to Kaggle to learn, collaborate and develop the state of the art in machine learning. This talk will cover some of the lessons on winning techniques we have learned from the Kaggle community.

2015

Meetup Summary - Winning Data Science Competitions

If you’ve never heard of kaggle, I guess the first question I have to ask is “how did you end up on DataScience.LA?” :) Kaggle is one of the foremost machine learning competition websites on the internet. Companies from GE to Criteo and everything in between create competitions. These competitions are in the form of a dataset, ranging from small to relatively large (up to many many gigabytes), a stated goal (such as predicting an event or finding a numeric value) and an evaluation criteria. The Kaggle community has grown in the last few years, so that now competitions often host thousands of participants!
R and Impala: it's better to KISS than using Java

R and Impala: it's better to KISS than using Java

One of the best things I like in working at CARD.com is that I am not only crunching R code in 24/7, but I also have the chance to interact with and improve the related data infrastructure with some interesting technologies. After joining the company in January, I soon realized that while Impala is a very powerful database for handling data that do not comfortably fit in MySQL, it’s still not as fast as one might expect when querying large amount of data from R. Sometimes I had to wait several minutes for a query to run! So I used this spare time to think about how to improve the workflow.
Announcing Meetup! Lior Abraham of Inter|Ana

Announcing Meetup! Lior Abraham of Inter|Ana

Click HERE to sign up on Eventbrite! This is the second event of the new Data Warehouse, Business Intelligence and Analytics meetup. Talks: 1. Eduardo Arino de la Rubia: MySQL to Vertica with Tungsten Replicator In this very (very) short talk, I will discuss how you can, for free, stream your MySQL data to a Vertica Community Edition cluster, and do near real-time analytics on up to 1TB of data.

PyDSLA Video: Carlos Guestrin, CEO of DATO

On May 14th at the Venice Arts Center, the Los Angeles Python and Data Science communities were fortunate to hear a talk from world-renowned expert and CEO of Dato, Carlos Guestrin. Often times when you have a meetup where a presenter is tightly identified with a company, the concern is that the presentation will fundamentally become a product pitch. We had nothing to be worried about in this case - Carlos presented for nearly an hour on a wide range of subjects from how the Machine Learning pipeline has changed over time to Deep Learning!
Data Science @ Whisper

Data Science @ Whisper

Where were you on the evening of Monday, March 23rd? Do you remember what you were up to? If you were one of the over 100 attendees to the latest installment of Szilard’s Data Science Meetup, you definitely remember! You were at Cross Campus Santa Monica, receiving a teaser on fundamentals of probabilistic programming by LA ML Meetup founder Rob Zinkov along with a detailed master class on modern machine learning architectures and approaches by Los Angeles’ own Whisper!