↓ Skip to main content

Hadoop

2016

LA Data Warehouse, Business Intelligence and Analytics - Jihoon Son

LA Data Warehouse, Business Intelligence and Analytics - Jihoon Son

Tickets available HERE Talk: Jihoon Son Presents - Introduction to Apache Tajo: Future of Data Warehouse Abstract: Apache Tajo is a data warehouse system for Web-scale data. It provides virtual integration of a multitude of diverse data sources, thereby facilitating easy and rapid data integration which has been regarded as an essential, but heavy step in business intelligence. In addition, it has a fault-tolerable distributed query engine for accelerating query speed. With the “query federation” and “distributed processing” capacities, Tajo is capable of providing users with reliable and efficient analysis of Web-scale data spread on multiple sources. I will introduce Apache Tajo including its overall architecture, current state and challenges, and discuss advantages what Tajo can bring to users. In addition, I will give a brief demo of Tajo.
2015

R and Impala: it's better to KISS than using Java

R and Impala: it's better to KISS than using Java

One of the best things I like in working at CARD.com is that I am not only crunching R code in 24/7, but I also have the chance to interact with and improve the related data infrastructure with some interesting technologies. After joining the company in January, I soon realized that while Impala is a very powerful database for handling data that do not comfortably fit in MySQL, it’s still not as fast as one might expect when querying large amount of data from R. Sometimes I had to wait several minutes for a query to run! So I used this spare time to think about how to improve the workflow.
DW/BI/Analytics Meetup Summary: Inaugural Event

DW/BI/Analytics Meetup Summary: Inaugural Event

The LA Data Warehouse, Business Analytics and Analytics meetup had a fantastic first event with a great audience (full house), an awesome host (thanks Edmunds: Punnoose for taking the lead and the Team onsite and helping) and a great mix of 3 talks overviewing the field.

2014

Data Science Toolbox Survey Results... Surprise! R and Python win

Data Science Toolbox Survey Results... Surprise! R and Python win

This is a re-publication of a blog post from a blog I created not long before we got the idea to start DataScience.LA, and in many aspects it is the genesis of DSLA (the blog’s name, the people getting together - thanks Eduardo, Amelia and Leigh). It was also the spark that lead to the creation of the Python Data Science LA meetup.
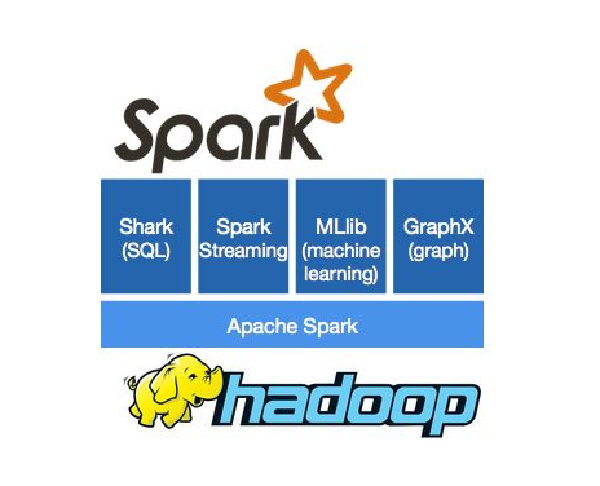
The case for Apache Spark

The case for Apache Spark

·3 mins
I have been following Big Data, Hadoop in particular, for the past four years and a lot has changed since then. At the time I was looking for the next big wave of technologies, especially on the back end of development as that was my forte at the time. After our initial introduction, the more I learned the more I felt Hadoop was the right tool to get the job done. Focusing upon the development aspects of job vs actual maintenance of the servers/cluster has always been a no-brainer for me. Now that Hadoop has been adopted by a wide variety of industries and has grown quite popular, it has become much more apparent that there are indeed areas where Hadoop is lacking. Security and real-time analytics are two of these concerns which both affect real-time processing and reporting, but fortunately there is a lot of current work happening to address these limitations. Consequently, there is a group of big data vendors who are investing a large number of resources as a remedy, bringing us newer tools such as Yarn, Tez, Storm, etc. Also, acquisitions of XA Secure by Hortonworks and Gazzang by Cloudera are contributing to the solving these issues around security.