↓ Skip to main content

predictive modeling

2016

XGBoost workshop and meetup talk with Tianqi Chen

XGBoost workshop and meetup talk with Tianqi Chen

XGBoost is a fantastic open source implementation of Gradient Boosting Machines, a general purpose supervised learning method that achieves the highest accuracy on a wide range of datasets in practical applications. Deep learning is all the hype now, but apart from specific domains such as images, speech or text (i.e. problems with higher-level abstractions to be learnt and/or perception problems, where deep learning achieved some remarkable results indeed), it is usually outperformed by Gradient Boosting in a majority of general business domains and supervised learning applications. Proof of this and also because XGBoost has an easy-to-use interface from both R and Python, XGBoost has become a favorite tool in Kaggle competitions. Besides feature engineering, cross-validation and ensembling, XGBoost is a key ingredient for achieving the highest accuracy in many data science competitions and more importantly in practical applications.
XGBoost: meetup announcement

XGBoost: meetup announcement

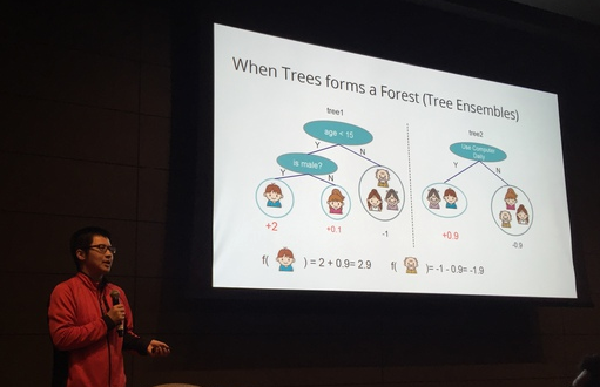
XGBoost is a fantastic open source implementation of Gradient Boosting Machines, one of the most accurate general purpose supervised learning algorithms. With interfaces from both R and Python among others, it has become a favorite tool in Kaggle competitions, and it’s also widely used in real-world applications. In this meetup we’ll have a talk from the best person on the topic,Tianqi Chen, main author of XGBoost.

2015

2014

Data Science Toolbox Survey Results... Surprise! R and Python win

Data Science Toolbox Survey Results... Surprise! R and Python win

This is a re-publication of a blog post from a blog I created not long before we got the idea to start DataScience.LA, and in many aspects it is the genesis of DSLA (the blog’s name, the people getting together - thanks Eduardo, Amelia and Leigh). It was also the spark that lead to the creation of the Python Data Science LA meetup.

A Conversation with Max Kuhn - The useR! 2014 Interview

The Interview # In the video above, Max provides some amazing insights into the why and how of caret, an R package he created. He also discusses his book on Applied Predictive Modeling which he co-authored with Kjell Johnson, including details on how he set out to write the book he wished he would have had. As a special bonus, Max also describes Quinlan’s C5.0, an alternate “forest of decision trees” algorithm, the secrets of which were hidden behind commercial licensing for years - and which has recently been ported and made available to the R ecosystem. Whether you are a beginner just getting your feet wet with R and predictive modeling, or a seasoned data scientist, this interview has something for everyone.