
↓ Skip to main content

scikit-learn

2015

Benchmarking Random Forest Implementations

Benchmarking Random Forest Implementations

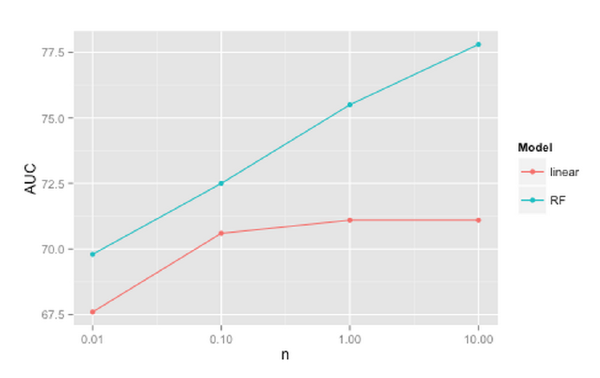
I currently have the need for machine learning tools that can deal with observations of the order of 10 millions in the context of binary classification. That kind of data is a few GBs in size and it fits comfortably nowadays in the RAM of a decent single machine. It is a trivial task for linear models, as there are plenty of open source tools that can train a logistic regression with this amount of data on a single machine in a few seconds, even while using only 1 processor core (many of these tools are single-threaded). Linear models are also the gold standard of large-scale machine learning that can run on clusters, processing very large distributed datasets.
PyDSLA - Blaze: Connecting analysts to big computation

PyDSLA - Blaze: Connecting analysts to big computation

Join PyDSLA for a talk by Matthew Rocklin about the high level APIs being developed for Python for expressive data manipulation and analysis. Summary: Pandas and NumPy serve us well. They give interactive high-level access to efficient low-level code. As datasets grow larger than memory this low-level code becomes obsolete but the high-level interface remains valuable. Blaze connects that high-level interface to a number of other computational systems like SQL, Mongo, or Spark, extending the scope of interactive analysis. In this talk we go over common use cases and Blaze as well as a bit of its internal design.