What has Kaggle learned from 2 million machine learning models?
Anthony Goldbloom, founder and CEO of Kaggle
UPDATE:Video recording of the talk available here
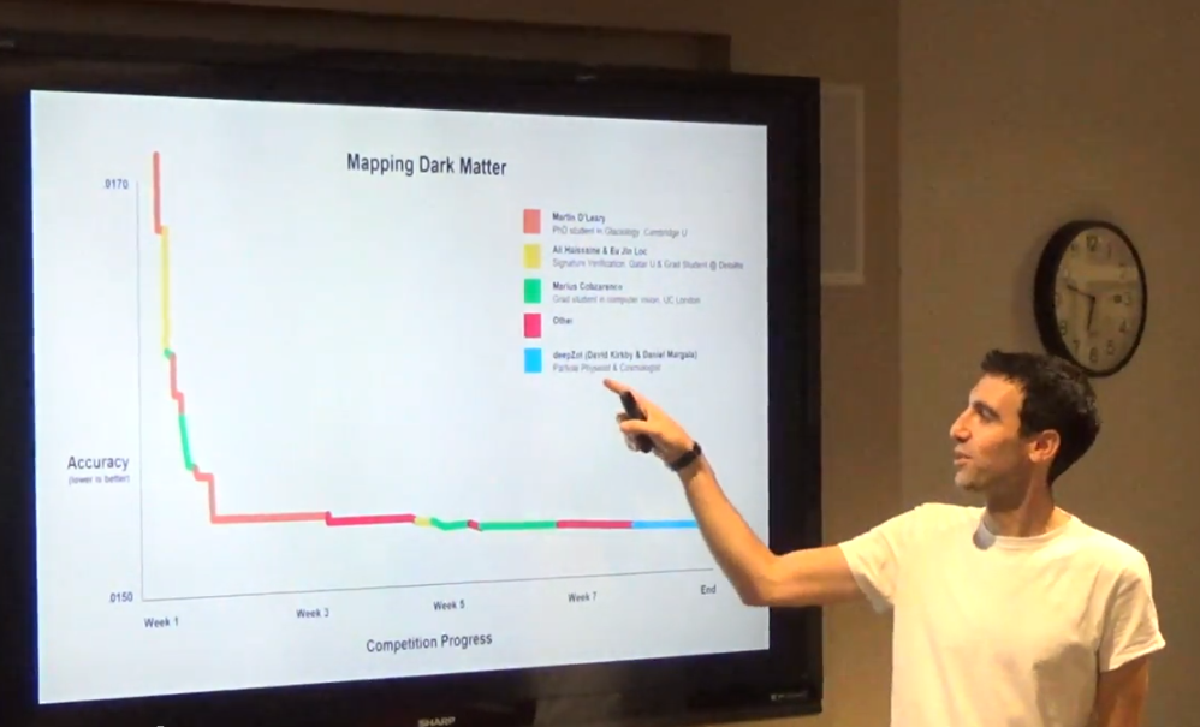
Kaggle is a community of almost 450K data scientists who have built almost 2MM machine learning models to participate in our competitions. Data scientists come to Kaggle to learn, collaborate and develop the state of the art in machine learning. This talk will cover some of the lessons on winning techniques we have learned from the Kaggle community.
Speaker bio: Anthony Goldbloom is the founder and CEO of Kaggle. In 2011 & 2012, Forbes Magazine named Anthony as one of the 30 under 30 in technology, in 2013 the MIT Tech Review named him one of top 35 innovators under the age of 35 and the University of Melbourne awarded him an Alumni of Distinction Award. He holds a first call honors degree in Econometrics from the University of Melbourne. Anthony has published in the The Economist and the Harvard Business Review.
Date: February 4, 2016
Timeline:
- 6:00pm arrival, food/drinks and networking
- 6:30pm talk starts
You must have a confirmed RSVP and please arrive by 6:25pm the latest. Please RSVP here on Eventbrite and if the event is already full,sign up to the DataScience.LA priority mailing list to increase your change in getting in next time (we announce all events there first before publicizing on www.datascience.la or meetup.com).
Venue: Hulu, 2500 Broadway 2nd Floor, Santa Monica, CA 90404
Thanks Hulu for hosting and for food/drinks!
Parking: There is some limited street parking around. There is a parking garage underneath, but tickets will not be validated.